


ENTERPRISE RAG & KNOWLEDGE ENGINEERING
Enterprise RAG That Turns Your Knowledge Into a Trusted AI Asset
We build retrieval-augmented generation systems that give your teams accurate, citable answers from millions of internal documents, with zero hallucinations on the data that matters.


Unlock the Power of Your Corporate Data with Complete Sovereignty
Our practice covers everything from knowledge base architecture and vector search to governance, evaluation, and ongoing knowledge curation.
Knowledge Base Architecture
We design knowledge architectures covering data sources, ingestion pipelines, chunking strategies, metadata, indexing, and content relationships to support reliable retrieval across enterprise knowledge.
Vector Search & Hybrid Retrieval
We design and tune semantic, keyword, and hybrid retrieval approaches using vector databases and enterprise search technologies, with reranking and filtering strategies tailored to your knowledge sources and query patterns.
Enterprise Document & Data Ingestion
We build pipelines that handle PDFs, Word docs, Confluence, SharePoint, Notion, ticketing systems, and email archives, with incremental updates as content changes.
Permission-Aware Retrieval
AHT Tech design retrieval workflows that incorporate existing access permissions and identity controls, helping ensure users receive information only from knowledge sources they are authorized to access.
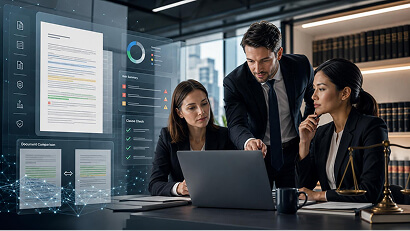
Grounded Responses, Citations & Guardrails
We combine source grounding, citations, retrieval thresholds, and response controls to reduce unsupported answers and give users greater visibility into the information behind AI-generated responses.
RAG Evaluation & Continuous Tuning
Our team runs golden-set evaluations, A/B tests on retrieval and generation, and feedback loops that improve answer quality month over month.
Knowledge Curation & Governance
We help define content ownership, review processes, metadata standards, access policies, and knowledge lifecycle practices so enterprise knowledge can remain relevant, governed, and easier to maintain over time.
Our Worldwide Customers










OUR TECHNOLOGY STACKS
The Tools Behind Our Recommendations
We work across every major LLM, cloud, and data stack so our recommendations are grounded in what actually fits your environment.






Protecting Your Data Is Our Top Priority
How We Build Enterprise RAG Knowledge Systems
Our delivery approach focuses on retrieval quality, security, governance, and maintainability throughout the RAG lifecycle.
Contact Us
Use Case & Knowledge Scope Definition
We define target use cases, user questions, knowledge sources, access requirements, and success criteria to establish the scope and expected outcomes of the RAG system.

Data Pipeline & Indexing Setup
Our engineers build ingestion pipelines, design the chunking strategy, and populate the vector store with permission metadata baked in.

Retrieval & Response Optimization
We configure retrieval, reranking, grounding, and response strategies, then evaluate them against representative questions and test datasets to improve relevance and answer quality.

Security, Governance & User Validation
We validate access controls, retrieval behavior, audit requirements, and representative user scenarios, with user acceptance testing before production deployment.

Deploy, Monitor & Continuously Improve
We support controlled deployment and monitor retrieval patterns, user feedback, content changes, and system performance to identify opportunities for ongoing tuning and knowledge-base improvement.
Case studies

PUMA is a global company based in Germany that creates and produces sports and leisure footwear, clothing, and accessories. PUMA has updated and redesigned its mobile websites in over 24 locations across the world, a move that underlines the rising significance of mobile.

Retailer ALDO Improve 1-To-1 Communications with Customers Through Salesforce
Aldo Bensadoun opened his own store in downtown Montreal in 1972 with the audacious goal of becoming the "brand that cares," following in the footsteps of his shoe salesman father and cobbler grandfather who later owned businesses. Since then, Bensadoun has expanded Aldo into a global footwear chain with more than 2,000 locations across more than 100 nations, carrying on the massively successful tradition of style and craftsmanship started by his family. The founding principles of Bensadoun have persisted as well; "love" is listed among its official corporate values.

Salesforce Helps FCB Group Optimize Productivity
FCB Group has been helping Australian businesses about the murky waters of workplace relations and employment law for 25 years. FCB Group provides specialized guidance to hundreds of ASX-listed firms.FCB Group's client has recently expanded thanks to the company's recent commercial diversification, which now includes cloud-based HR technology platforms and migration services. The company currently provides services to around 12,500 clients across five different industry sectors thanks to its comprehensive approach to workplace legislation.
ABOUT AHT TECH
Why Partner With AHT Tech?

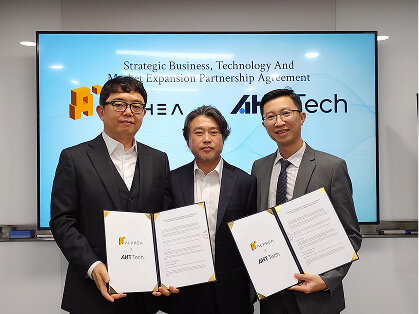
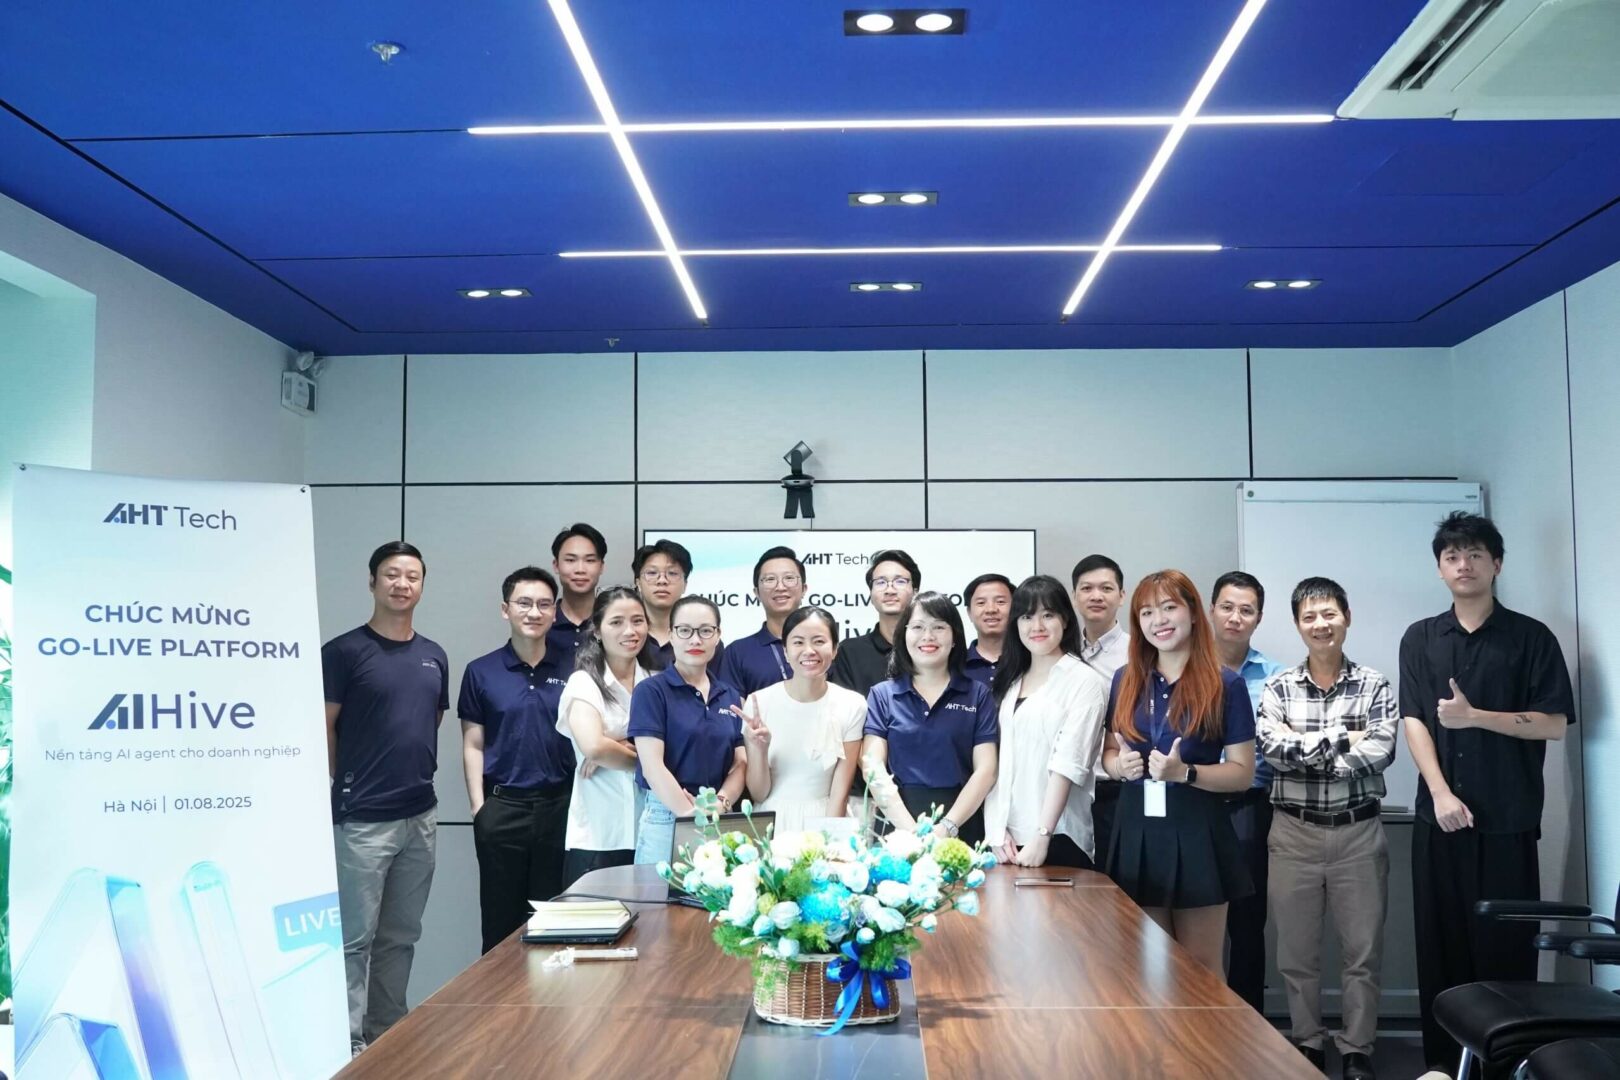
Global businesses trust AHT Tech for more than just technical support - they rely on us as top strategic partners to navigate complexity and drive efficient transformation.
AI-First Innovation
By integrating AI-first solutions into our core offerings, from predictive analytics to AI-driven eCommerce agents, AHT Tech ensure your infrastructure is smarter, faster, and ready for the next generation of digital commerce.
Deep Domain Expertise
With 19+ years of engineering, we bring specialized mastery to every project, our deep industry knowledge turns technical hurdles into competitive advantages.
Dedicated Global Support
Our global support model ensures your operations never sleep. We act as a seamless extension of your team, providing proactive monitoring and technical stewardship that guarantees your systems remain resilient and mission-ready.
Results-driven Performance Metrics
Every solution we engineer is anchored in measurable ROI and performance KPIs. By aligning our technical roadmap with your business outcomes, we ensure that digital transformation results in tangible growth and operational precision.
Let's Build the Future of Your Business with Our Enterprise RAG & Knowledge Engineering Service Today
The first step toward innovation is a simple conversation. We’re ready when you are.
Show on services pages
Frequently Asked Question
How is enterprise RAG different from a regular chatbot on top of ChatGPT?
A regular chatbot pulls from public data and often hallucinates. Enterprise RAG retrieves passages from your internal documents and grounds every answer in them, with citations. The accuracy gap on internal questions is usually 40 to 60 percentage points.
How do you prevent hallucinations in production?
We enforce citation requirements, set retrieval confidence thresholds, and block answers when the system cannot ground a response in source documents. Most clients see hallucination rates drop below 2% on internal queries.
Can your RAG system respect our existing document permissions?
Yes. We integrate with Active Directory, Okta, SharePoint permissions, and other access control systems so retrieval only returns chunks the requesting user is authorized to read.
How often does the knowledge base need updating?
Our pipelines support real-time, hourly, daily, or weekly sync depending on how fast your source content changes. Confluence and SharePoint usually run hourly, while contract repositories often run daily.
Which vector databases and embedding models do you support?
We work with Pinecone, Weaviate, Qdrant, Milvus, Elasticsearch, and pgvector, paired with embedding models from OpenAI, Cohere, Voyage, or open-source alternatives like BGE and E5. The choice depends on data volume, latency, and budget.